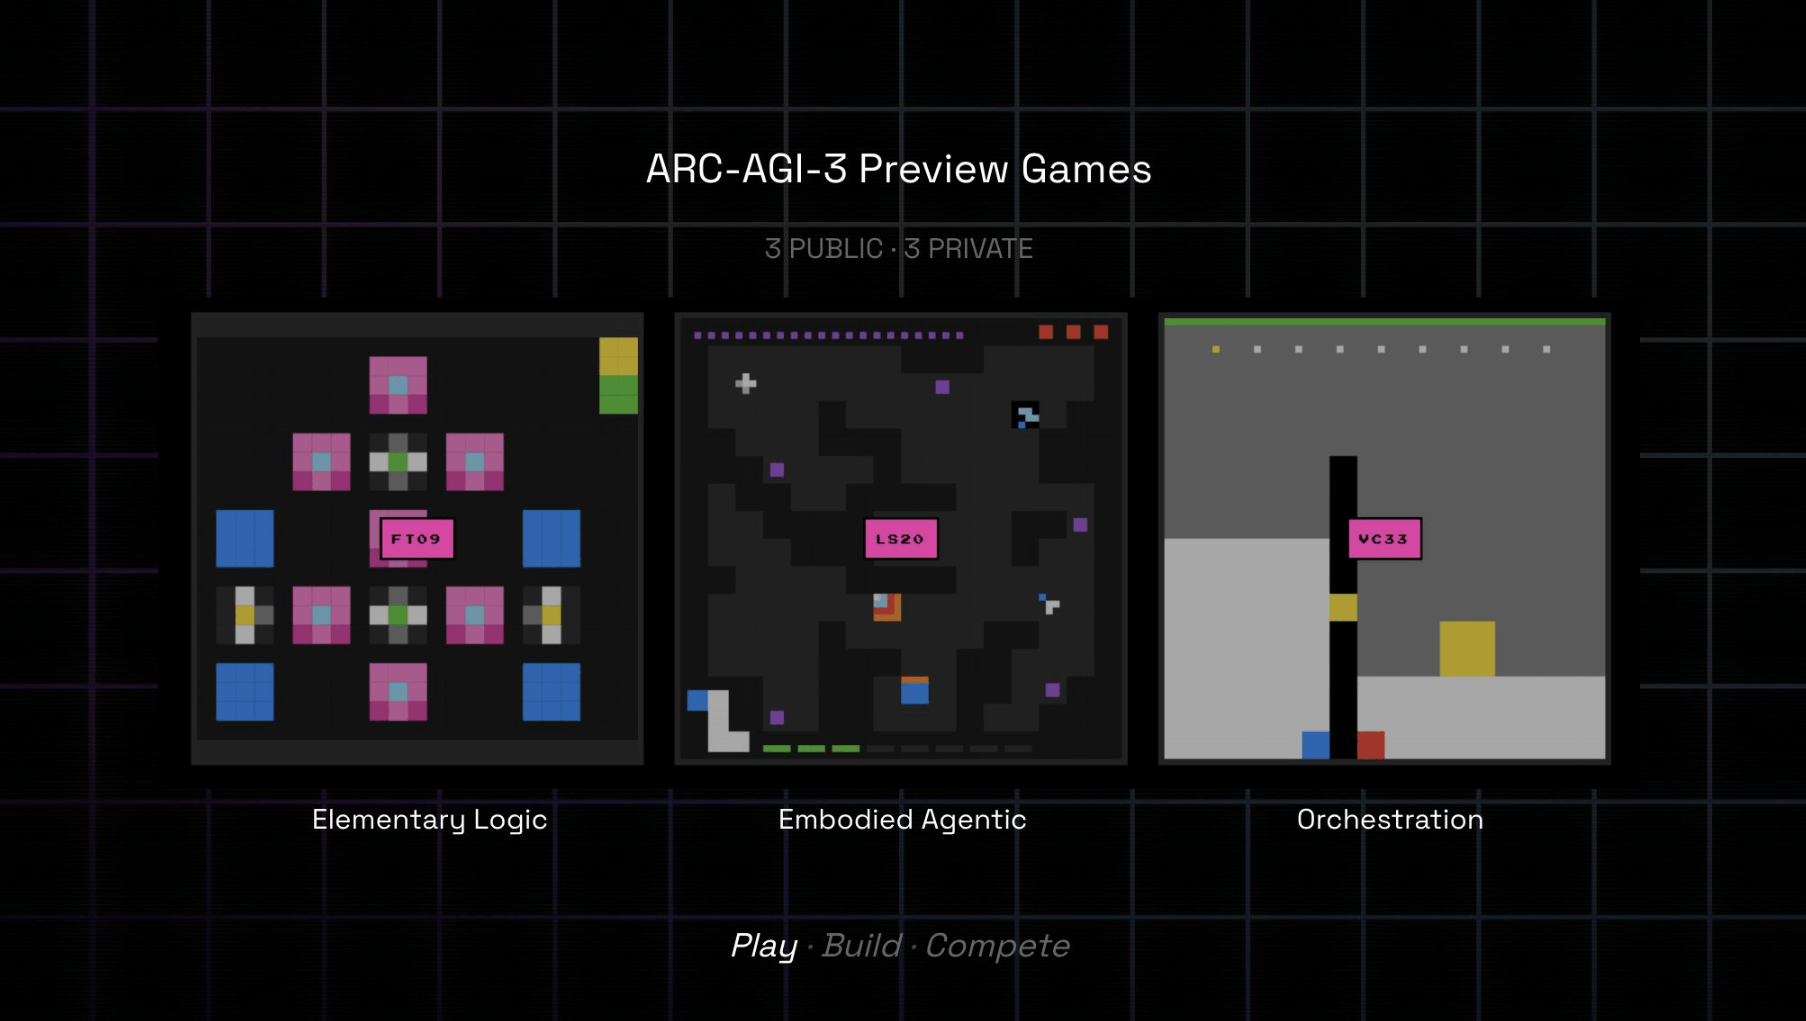
New ARC-AGI-3 benchmark shows that humans still outperform LLMs at pretty basic thinking
ARC-AGI-3 aims to test how well AI systems can handle brand new problems. While people breeze through the challenges, the latest AI models still come up short.<br /> The article New ARC-AGI-3 benchmark shows that humans still outperform LLMs at pretty basic thinking appeared first on THE DECODER. [...]
Rating
Innovation
Pricing
Technology
Usability
We have discovered similar tools to what you are looking for. Check out our suggestions for similar AI tools.
Moonshot's Kimi K2 Thinking emerges as leading open source AI, outperforming GPT-5, Claude Sonnet 4.5 on key benchmarks
Even as concern and skepticism grows over U.S. AI startup OpenAI's buildout strategy and high spending commitments, Chinese open source AI providers are escalating their competition and one has e [...]
AI IQ is here: a new site scores frontier AI models on the human IQ scale. The results are already dividing tech.
For decades, the IQ test has been one of the most familiar — and most contested — yardsticks for human intelligence. Now, a startup project called AI IQ is applying the same metaphor to artificial [...]
Samsung AI researcher's new, open reasoning model TRM outperforms models 10,000X larger — on specific problems
The trend of AI researchers developing new, small open source generative models that outperform far larger, proprietary peers continued this week with yet another staggering advancement.Alexia Jolicoe [...]
Thinking Machines open sources first multimodal language model, Inkling, focused on low cost and 'resistance to censorship'
Enterprises looking to move more of their agentic AI workloads to open weights models they can customize, control and run on-premises or in virtual private clouds have a strong new contender to consid [...]
Microsoft and OpenAI gut their exclusive deal, freeing OpenAI to sell on AWS and Google Cloud
Microsoft and OpenAI on Monday announced a sweeping overhaul of the partnership that has defined the commercial AI era, dismantling key pillars of exclusivity and revenue-sharing that bound the two co [...]
Thinking Machines shows off preview of near-realtime AI voice and video conversation with new 'interaction models'
Is AI leaving the era of "turn-based" chat?Right now, all of us who use AI models regularly for work or in our personal lives know that the basic interaction mode across text, imagery, audio [...]
ARC-AGI-3 offers $2M to any AI that matches untrained humans, yet every frontier model scores below 1%
The new ARC-AGI-3 benchmark drops AI systems into interactive game environments that humans solve with ease. No frontier model breaks the 1 percent mark because the benchmark strips away their biggest [...]

Even the latest AI models make three systematic reasoning errors, ARC-AGI-3 analysis shows
The ARC Prize Foundation analyzed 160 game runs of OpenAI's GPT-5.5 and Anthropic's Opus 4.7 on the ARC-AGI-3 benchmark. Three systematic error patterns explain why both models stay below 1 [...]