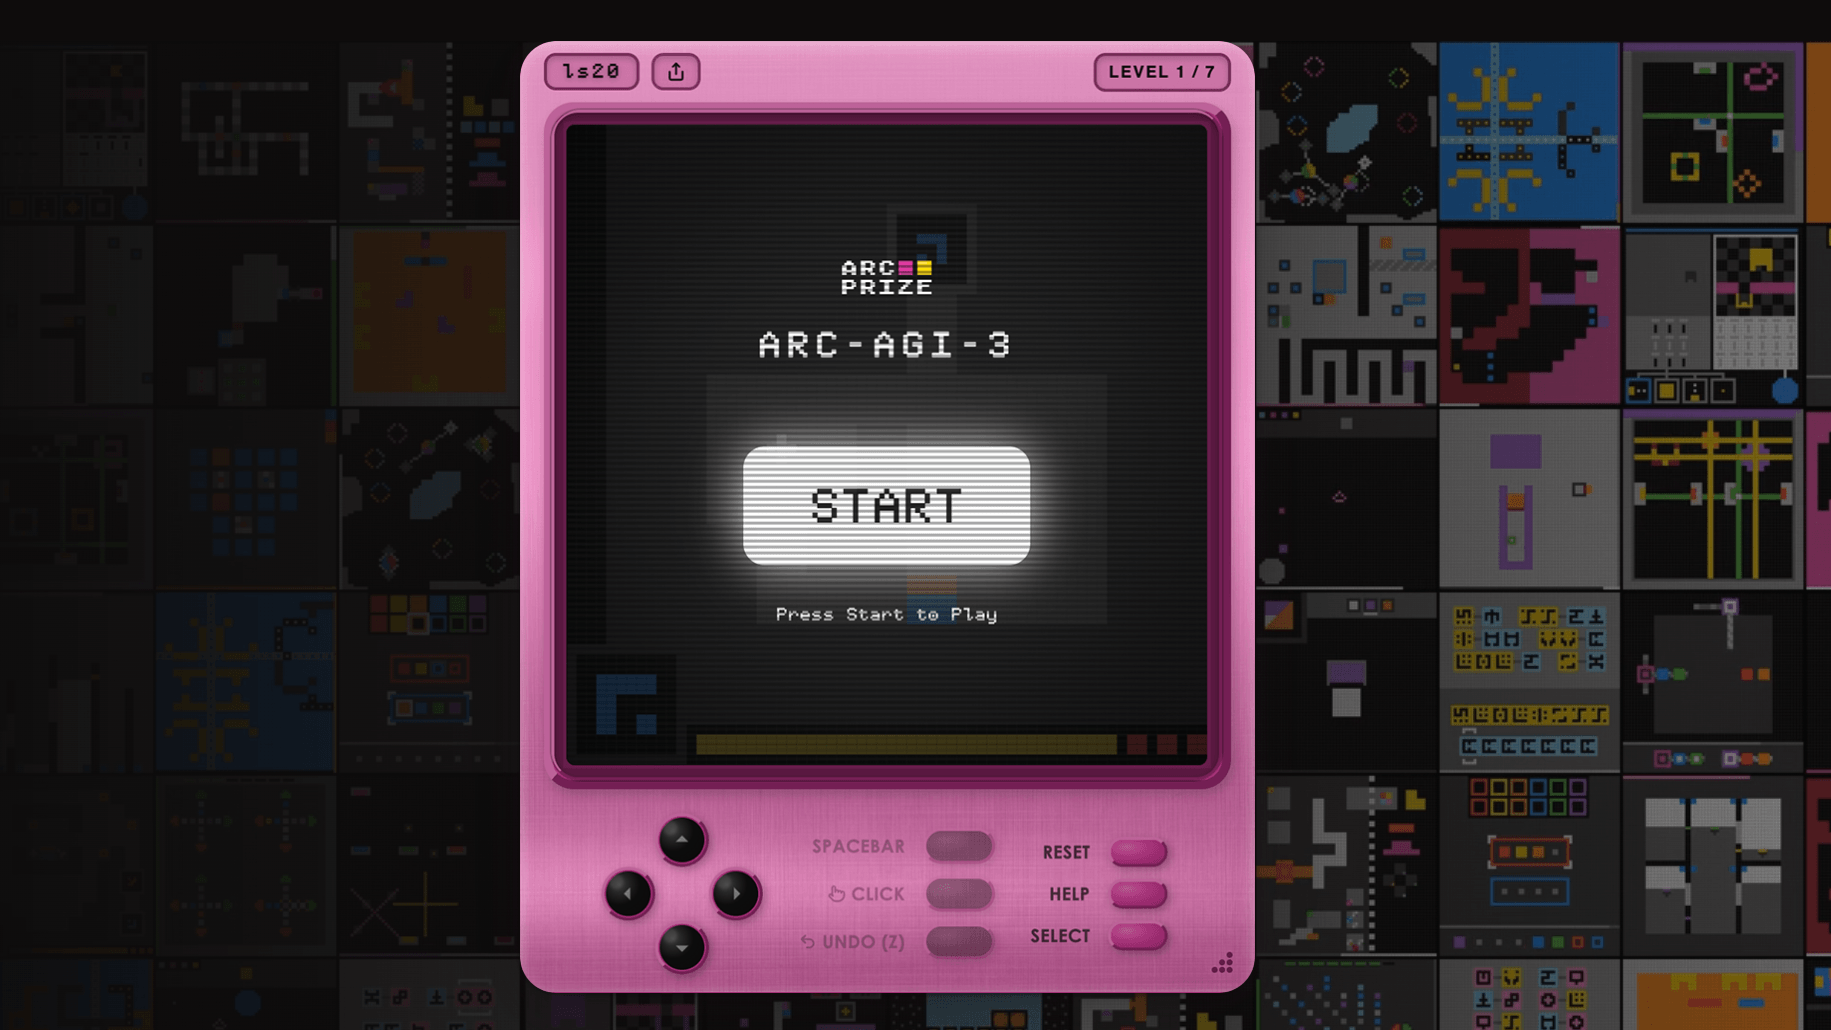
ARC-AGI-3 offers $2M to any AI that matches untrained humans, yet every frontier model scores below 1%
The new ARC-AGI-3 benchmark drops AI systems into interactive game environments that humans solve with ease. No frontier model breaks the 1 percent mark because the benchmark strips away their biggest advantages.<br /> The article ARC-AGI-3 offers $2M to any AI that matches untrained humans, yet every frontier model scores below 1% appeared first on The Decoder. [...]
Rating
Innovation
Pricing
Technology
Usability
We have discovered similar tools to what you are looking for. Check out our suggestions for similar AI tools.
AI IQ is here: a new site scores frontier AI models on the human IQ scale. The results are already dividing tech.
For decades, the IQ test has been one of the most familiar — and most contested — yardsticks for human intelligence. Now, a startup project called AI IQ is applying the same metaphor to artificial [...]
Microsoft and OpenAI gut their exclusive deal, freeing OpenAI to sell on AWS and Google Cloud
Microsoft and OpenAI on Monday announced a sweeping overhaul of the partnership that has defined the commercial AI era, dismantling key pillars of exclusivity and revenue-sharing that bound the two co [...]
Samsung AI researcher's new, open reasoning model TRM outperforms models 10,000X larger — on specific problems
The trend of AI researchers developing new, small open source generative models that outperform far larger, proprietary peers continued this week with yet another staggering advancement.Alexia Jolicoe [...]
Microsoft AI chief says company was “set free” from OpenAI to pursue superintelligence
For three years, Microsoft's artificial intelligence story has been inseparable from OpenAI. The partnership — cemented by a cumulative investment exceeding $13 billion — gave Microsoft early [...]
SpaceXAI debuts Grok 4.6, overtaking Kimi K3's performance and matching GPT-5.6 Sol for world's third best on Artificial Analysis
Elon Musk's company SpaceXAI, formerly known as xAI, has released Grok 4.6, its latest frontier AI model, with a focus on long-running agents, coding and knowledge work — and a pricing strategy [...]
Anthropic launches Claude Opus 5, a cheaper AI model for coding, agents and enterprise workflows
Anthropic released Claude Opus 5 on Friday, a model the company says delivers nearly all the intelligence of its top-of-the-line Claude Fable 5 at half the cost — a launch that signals how the AI ra [...]
DeepSeek-V4 arrives with near state-of-the-art intelligence at 1/6th the cost of Opus 4.7, GPT-5.5
The whale has resurfaced. DeepSeek, the Chinese AI startup offshoot of High-Flyer Capital Management quantitative analysis firm, became a near-overnight sensation globally in January 2025 with the rel [...]

Even the latest AI models make three systematic reasoning errors, ARC-AGI-3 analysis shows
The ARC Prize Foundation analyzed 160 game runs of OpenAI's GPT-5.5 and Anthropic's Opus 4.7 on the ARC-AGI-3 benchmark. Three systematic error patterns explain why both models stay below 1 [...]
Amazon's new AI can code for days without human help. What does that mean for software engineers?
Amazon Web Services on Tuesday announced a new class of artificial intelligence systems called "frontier agents" that can work autonomously for hours or even days without human intervention, [...]