qz
Timken CEO Lucian Boldea explains 'elevate to outperform' strategy

Timken CEO Lucian Boldea explains 'elevate to outperform' strategy [...]

Rating

Innovation

Pricing

Technology

Usability

We have discovered similar tools to what you are looking for. Check out our suggestions for similar AI tools.
qz
Timken Company (The) (TKR) Hits Fresh High: Is There Still Room to Run?

Timken (TKR) is at a 52-week high, but can investors hope for more gains in the future? We take a look at the company's fundamentals for clues. [...]

Match Score: 49.55

qz
Timken (TKR) is a Great Momentum Stock: Should You Buy?

Does Timken (TKR) have what it takes to be a top stock pick for momentum investors? Let's find out. [...]

Match Score: 49.55

Destination
Microsoft's Phi-4-reasoning models outperform larger models and run on your laptop or phone

Microsoft is expanding its Phi series of compact language models with three new variants designed for advanced reasoning tasks.<br /> The article Microsoft's Phi-4-reasoning models outperfo [...]
Match Score: 27.12

Destination
OpenAI says its latest models outperform doctors in medical benchmark

OpenAI has released a new benchmark for testing AI systems in healthcare. Called HealthBench, it's designed to evaluate how well language models handle realistic medical conversations. According [...]

Match Score: 27.12

venturebeat
Researchers automated LLM reasoning strategy design and cut token usage by 69.5%

Test-time scaling (TTS) has emerged as a proven method to improve the performance of large language models in real-world applications by giving them extra compute cycles at inference time. However, TT [...]
Match Score: 24.31

venturebeat
When dirt meets data: ScottsMiracle-Gro saved $150M using AI

How a semiconductor veteran turned over a century of horticultural wisdom into AI-led competitive advantage For decades, a ritual played out across ScottsMiracle-Gro’s media facilities. Every few w [...]

Match Score: 24.09

Destination
AI agents outperform human teams in hacking competitions

A recent series of cybersecurity competitions organized by Palisade Research shows that autonomous AI agents can compete directly with human hackers, and sometimes come out ahead.<br /> The arti [...]

Match Score: 21.70

Destination
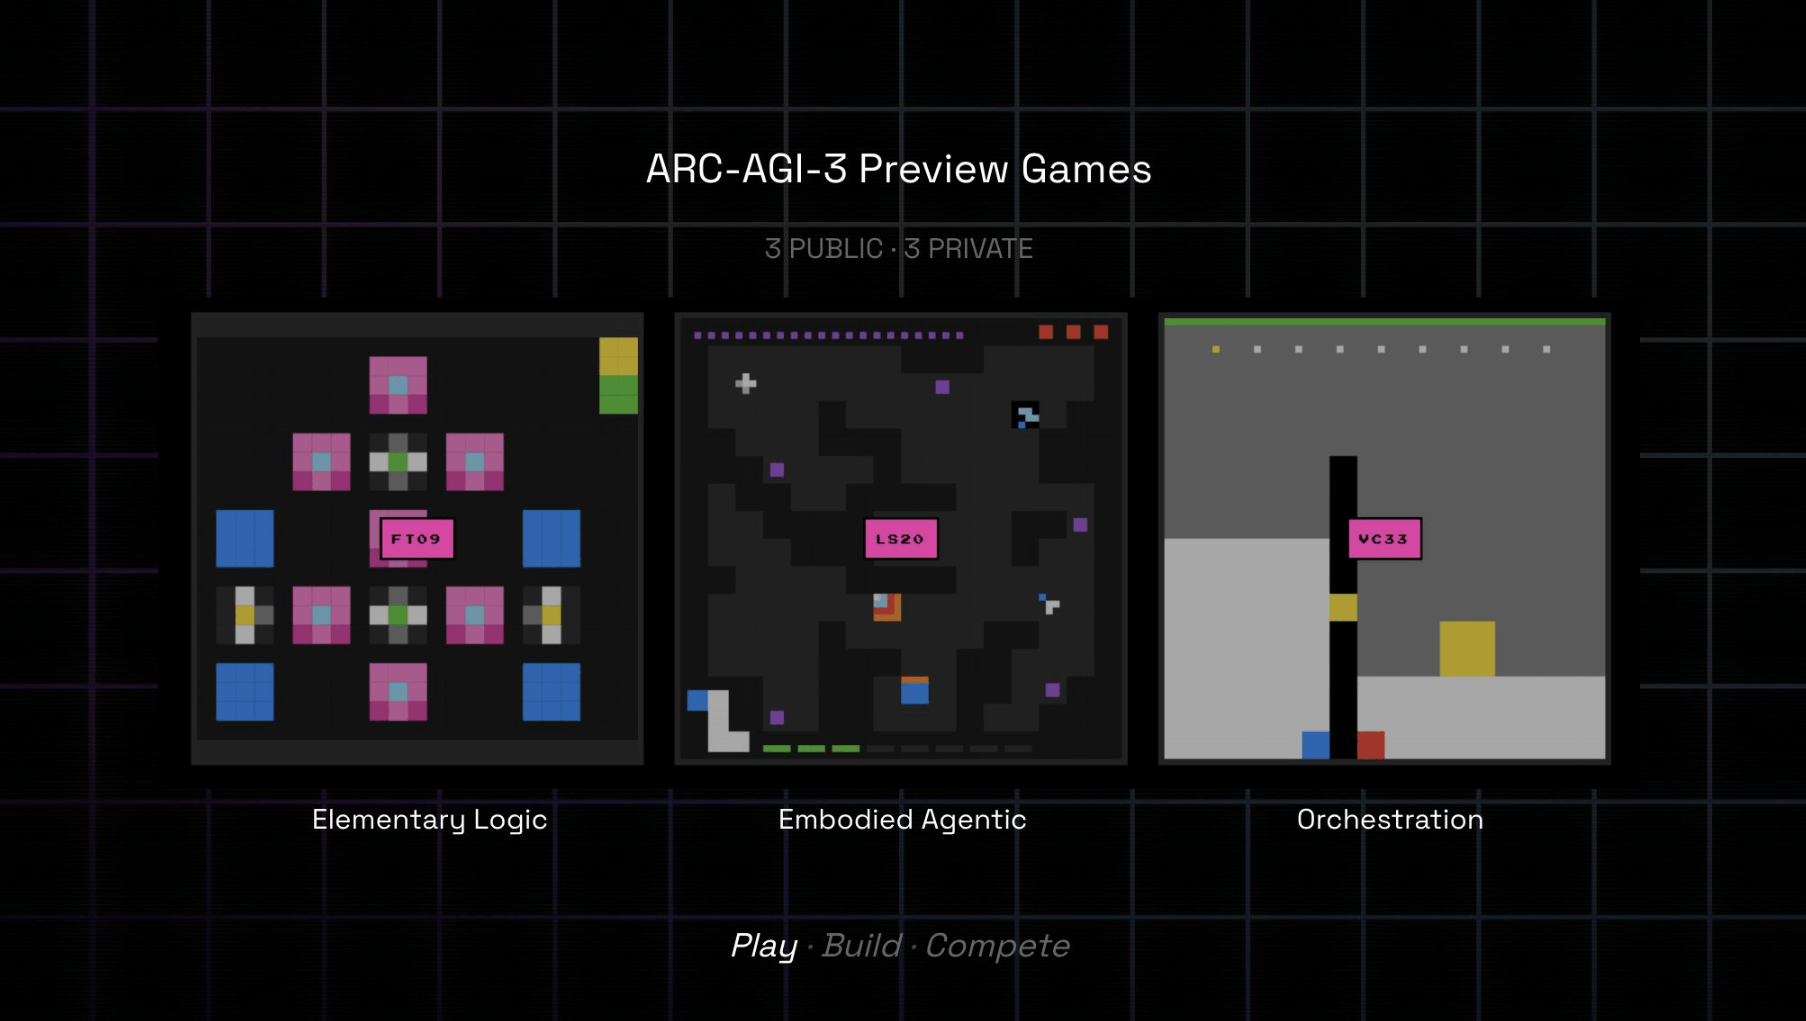
New ARC-AGI-3 benchmark shows that humans still outperform LLMs at pretty basic thinking

ARC-AGI-3 aims to test how well AI systems can handle brand new problems. While people breeze through the challenges, the latest AI models still come up short.<br /> The article New ARC-AGI-3 be [...]

Match Score: 21.70

Destination
Cisco bets its small open cybersecurity models can outperform GPT-5.5 at vulnerability detection for a fraction of the cost

Cisco has released two small, open-source AI models for cybersecurity that detect about 150 times more vulnerabilities per dollar than large AI agents, according to the company's own tests.<br [...]

Match Score: 21.70